Problem Formulation
This page defines the finite-horizon MPC problem solved by affine_mpc.
Discrete-Time Affine Model
The system model is assumed to be discrete-time, affine, and time-invariant:
where \(\bm{w}\) is the model offset. It holds everything that does not depend on the state or input, such as gravity, the operating point of an affine approximation, or a disturbance estimate (see Modeling Patterns).
Base Problem
This generates a dynamically feasible input trajectory by minimizing state tracking error while respecting input limits.
In affine_mpc, the parameterization mapping function \(g_k\) is implemented with B-splines,
so saturating the control points saturates the entire input trajectory as well
(due to the convex hull property of B-splines).
A custom basis has no such property, so its sampled inputs are always saturated instead.
Nomenclature
MPC Terms
| Symbol | Meaning |
|---|---|
| \(n\) | state dimension |
| \(m\) | input dimension |
| \(n_b\) | number of bounded states (bounded_states; \(n_b = n\) by default) |
| \(T\) | number of steps in the prediction horizon |
| \(\eta\) | number of control points that parameterize the input trajectory |
| \(\bm{x}_k \in \R^n\) | state vector at horizon step \(k\) |
| \(\bm{u}_k \in \R^m\) | input vector applied at horizon step \(k\) |
| \(A \in \R^{n \times n}\) | discrete-time state matrix |
| \(B \in \R^{n \times m}\) | discrete-time input matrix |
| \(\bm{w} \in \R^n\) | discrete-time model offset |
| \(\bm{u}_{-1} \in \R^m\) | previous input, applied before the current horizon |
| \(\bm{c}_i \in \R^m\) | control point vector at index \(i\) |
| \(\bm{x}_{\mathrm{ref},k} \in \R^n\) | reference state at horizon step \(k\) |
| \(\bm{c}_{\mathrm{ref},i} \in \R^m\) | reference control point at index \(i\) |
| \(\bm{u}_{\mathrm{ref},k} \in \R^m\) | reference input at horizon step \(k\) (InputCostMode::Trajectory) |
| \(Q \in \R^{n \times n} \succeq 0\) | diagonal state weights |
| \(Q_{\mathrm{f}} \in \R^{n \times n} \succeq 0\) | diagonal terminal state weights |
| \(R \in \R^{m \times m} \succeq 0\) | diagonal input weights, on the control points or the sampled inputs (input_cost) |
| \(R_\Delta \in \R^{m \times m} \succeq 0\) | diagonal input rate weights |
| \(\bm{u}_{\min}, \bm{u}_{\max} \in \R^m\) | input limits |
| \(\bm{x}_{\min}, \bm{x}_{\max} \in \R^{n_b}\) | state limits of the bounded states |
| \(\bm{u}_{0,\mathrm{slew}} \in \R^m\) | slew rate limit of the initial input |
| \(\bm{u}_{\mathrm{slew}} \in \R^m\) | slew rate limit per sample step, on \(\bm{u}_k - \bm{u}_{k-1}\) for \(k \geq 1\) |
| \(\bm{s} \in \R^{n_b}\) | slack of the soft state bounds, one per bounded state |
| \(\bm{\rho}_1, \bm{\rho}_2 \in \R^{n_b}\) | L1 and L2 penalties of the slack |
| \(n_h\), \(n_{h,\mathrm{f}}\) | number of general and terminal constraints |
| \(H_x \in \R^{n_h \times n}\), \(H_u \in \R^{n_h \times m}\) | state and input matrices of the general constraints |
| \(\bm{h}_{\min}, \bm{h}_{\max} \in \R^{n_h}\) | bounds of the general constraints |
| \(H_{\mathrm{f}} \in \R^{n_{h,\mathrm{f}} \times n}\) | state matrix of the terminal constraints |
| \(\bm{h}_{\mathrm{f},\min}, \bm{h}_{\mathrm{f},\max} \in \R^{n_{h,\mathrm{f}}}\) | bounds of the terminal constraints |
Optional Terms
Input Cost
The input cost is chosen with Options::input_cost (InputCostMode): Off (the default), ControlPoints, or Trajectory.
Both modes use the same diagonal weight \(R\), set with setInputWeights() (it defaults to ones), and differ in where it is evaluated.
InputCostMode::ControlPoints weights the control points:
InputCostMode::Trajectory weights the sampled inputs \(\bm{u}_k\) over the horizon:
In unconstrained LQR-style formulations, an input penalty is typically used to regularize control effort, whereas MPC can also enforce hard input limits directly without an input regularizing term.
When you may want to use it:
- You specifically want to minimize control effort or energy (a zero reference, the default)
- You want to stay near an equilibrium value \(\bm{u}_e\) (
setReferenceInput()) - You have a reference input trajectory, perhaps from using differential flatness (
setReferenceInputTrajectory()withTrajectory)
Which mode to choose:
The two modes are the same up to a scale when every control point influences the same number of samples (e.g. move-blocking with equal blocks of length \(L\), where Trajectory with \(R\) equals ControlPoints with \(L R\)).
They differ when control points influence different numbers of samples: move-blocking with unequal blocks (Trajectory weights each block by its length), geometric knots, and custom bases, whose coefficients may have no physical meaning.
ControlPointsis the cheaper choice: it only adds to the diagonal of the cost matrix. Its reference is a set of control points (setReferenceInputControlPoints()), or a constant input (setReferenceInput(), B-splines only).Trajectoryweights the input trajectory itself, so \(R\) means the same thing for every parameterization, including a custom basis. Its reference is a sampled trajectory (setReferenceInputTrajectory()), which need not lie in the span of the basis, or a constant input (setReferenceInput(), for any basis). It adds a banded block to the cost matrix (dense for a custom basis), which costs a little more per solve.
Each mode keeps its own reference form, so the reference setter of the other mode throws std::logic_error (RuntimeError in Python).
Changing a reference only updates the QP vector \(\bm{q}\); changing \(R\) updates the cost matrix.
Input Rate Cost
This penalizes changes of the sampled inputs, starting from the previous input \(\bm{u}_{-1}\).
Enable it with use_input_rate_cost and set \(R_\Delta\) with setInputRateWeights() (it defaults to ones).
The previous input is stored after every solve that returns Success or SolvedInaccurate; call setPreviousInput() before the first solve, or after a failed solve if you applied a different input.
When you may want to use it:
- You want smooth inputs, e.g. to limit actuator wear or excite fewer high-frequency modes, without the hard limit of a slew rate constraint
- You compare parameterizations: like \(R\) with
InputCostMode::Trajectory, \(R_\Delta\) acts on the sampled inputs, so it penalizes the same input change equally for every basis, including a custom basis
Input Trajectory Saturation Constraint
The input limits are always enforced, and input_bounds chooses how.
The default, InputBoundMode::ControlPoints (InputBoundMode.ControlPoints in Python), saturates the control points only, which saturates the entire input trajectory due to the convex hull property of B-splines.
However, when the spline does not pass through its control points at the sample times, it becomes harder for the parameterization to utilize the full input range (it essentially becomes flattened).
This happens for any degree higher than 1, and for degree 1 when an active knot is not an integer.
InputBoundMode::Trajectory saturates the evaluated inputs instead, which adds more optimization constraints, but it lets the control points leave the input saturation range while the evaluated inputs remain saturated.
InputBoundMode::Refined lies between the two: it saturates the control points of the same spline after knot insertion, which still saturates the entire input trajectory but stays much closer to the limits than the original control points.
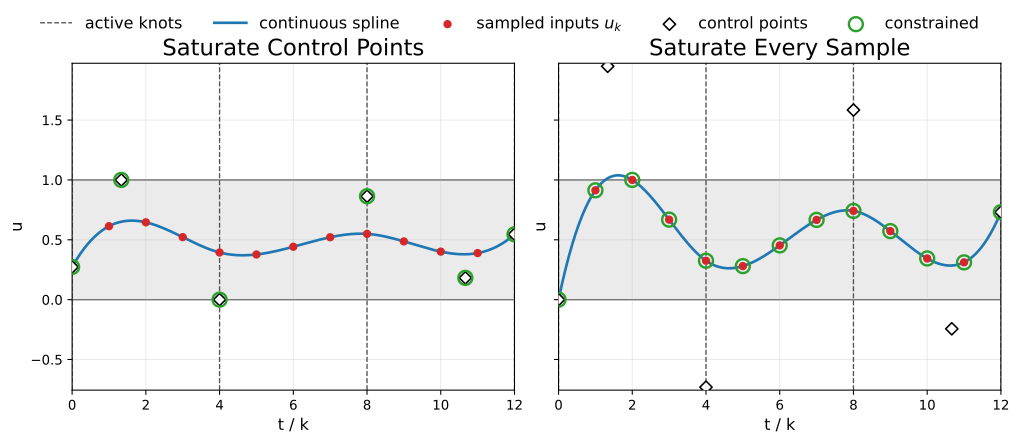 Saturating the control points (left) versus every sample (right) of a cubic spline.
Only the samples are constrained, so the continuous spline may cross a limit between samples.
How many constraints are added depends on the degree \(p\):
- \(p = 0\):
Trajectoryis the same asControlPoints, since the control points are the evaluated inputs. - \(p = 1\): the spline is linear between knots, so only the samples \(\lfloor t \rfloor\) and \(\lceil t \rceil\) adjacent to each active knot \(t\) are constrained (duplicates removed). This is exactly equivalent to constraining every sample and adds at most \(\min(T, 2\eta - 2)\) constraints per input. With integer knots it is the same as saturating the control points.
- \(p > 1\): every sample \(k = 0, \dots, T-1\) is constrained.
- A custom basis always constrains every sample, whatever
input_boundsis.
With \(p > 1\), Trajectory adds a row for every sample, so it can make OSQP slower on long horizons.
Refined adds about \(\max(T / L, 2(\eta - p)) + p\) rows per input instead, where \(L\) is refined_bound_interval, the longest knot interval after the insertion (in samples), and it uses the Trajectory rows whenever those are not more; for \(p \le 1\) it is the same as Trajectory, and a custom basis constrains every sample.
See Input Bounds for how the refined control points are built and how to choose \(L\).
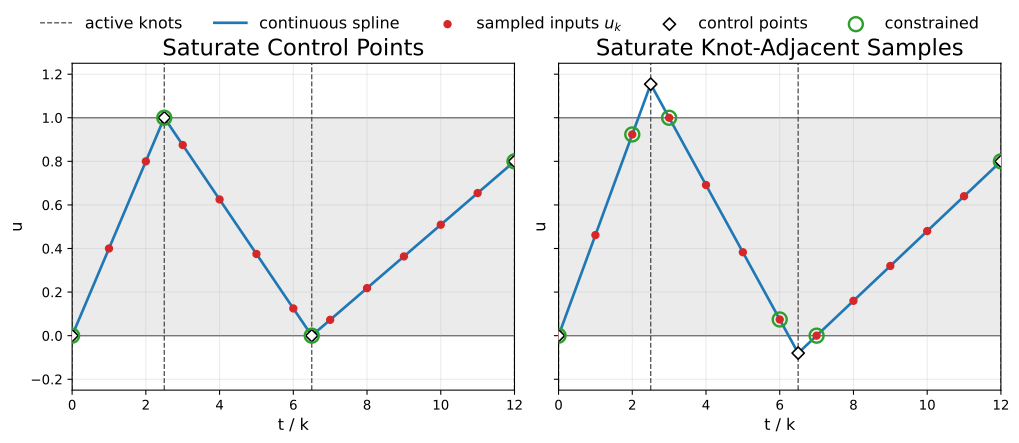 Saturating the control points (left) versus the knot-adjacent samples (right) of a degree 1 spline with non-integer knots.
When you may want to use it:
- When using a spline with degree higher than 1 to prevent input trajectory flattening
- When using a linear spline (degree 1) with non-integer knots
See Input Parameterization for more details on B-splines.
State Saturation Constraint
state_bounds chooses whether and how the states are bounded: StateBoundMode::Off (the default), Hard, or Soft (StateBoundMode.Hard and so on in Python).
Set the limits with setStateLimits(x_min, x_max).
Often only a few states need limits (e.g. roll and pitch of a quadrotor with 12 states).
List them in bounded_states; the limits then have one entry per listed state.
Every bounded state adds one constraint row per horizon step, and with the condensed formulation each row is dense, so bounding only the states that need it keeps the QP much smaller (in one 12-state example, bounding 2 states through infinite limits on the other 10 made the condensed solves 12 to 14 times slower than no state bounds at all).
Hard
When you may want to use it:
- Your system has physical state limits
- You want to provide extra stability (e.g., setting roll limits for an aircraft)
Danger
If your current state starts outside of the state limits, perhaps due to a disturbance, then hard bounds can cause the solver to immediately fail. Soft bounds avoid this.
Soft
One slack per bounded state, shared over the horizon, may widen both of its limits at the cost \(J_s\), set with setStateBoundPenalties(l1, l2) (there is no default).
The slack is the largest violation of its state over the horizon.
- The L1 penalty \(\bm{\rho}_1\) is exact: when it exceeds the bound's Lagrange multiplier, the solution equals the hard-bound solution whenever the limits can be met, and the limits are only violated when they can not.
- The L2 penalty \(\bm{\rho}_2\) alone always allows a small violation of an active limit (smaller for a larger penalty). With the L1 penalty it does not change the solution while the limits can be met.
- OSQP converges much faster with an L2 penalty on the scale of the state weights or larger: in one condensed example, an L1 penalty of 10 with an L2 penalty of 0.01 took about 1750 iterations, and with an L2 penalty of 100 it took about 500, against about 400 with hard bounds. A very large L1 penalty also slows OSQP.
- Polishing (in the solver settings) makes the solution match the hard-bound solution to round-off when the limits can be met.
When you may want to use it:
- Disturbances or model error can push the state past a limit, where hard bounds would make the problem infeasible
- Some limits are preferences rather than physical boundaries
Initial Input Slew Rate Constraint
This constrains the difference between the previous input and the first input in the horizon \(\bm{u}_0\) (which is the next to apply).
When you may want to use it:
- Your system is physically limited in how fast it can change inputs
Slew Rate Constraint
This limits how much each input may change from one sample step to the next over the horizon.
The limit \(\bm{u}_{\mathrm{slew}}\) (setSlewRate()) is in units of the input per sample step, not per second, so multiply a rate per second by the sample time.
The change from the previous input, \(\bm{u}_0 - \bm{u}_{-1}\), has its own limit (see above); enable both for a limit on every change.
slew_bounds chooses whether and how the limit is enforced: SlewBoundMode::Off (the default), ControlPoints, or Trajectory (SlewBoundMode.ControlPoints and so on in Python).
The limit means the same in both modes, as the input limits do with input_bounds.
-
ControlPointsbounds the differences of consecutive control points, one row per difference, as\[ |\bm{c}_i - \bm{c}_{i-1}| \leq \lambda_i \bm{u}_{\mathrm{slew}} \quad i=1,\dots,\eta-1, \qquad \lambda_i = \frac{\tau_{i+p} - \tau_i}{p} \quad (\lambda_i = 1 \text{ for } p = 0), \]with the knots in samples. The derivative of a degree \(p\) B-spline is a degree \(p-1\) B-spline with control points \((\bm{c}_i - \bm{c}_{i-1}) / \lambda_i\), so by the convex hull property these bounds keep the slope, and so every sampled change, within the limit. They are exact for \(p = 0\) (each change is zero or one difference) and for \(p = 1\) when every knot interval contains a whole sample step, e.g. integer knots one or more samples apart. Otherwise they are sufficient but conservative: the sampled changes stay inside the limit, but may not reach it. Where \(p + 1\) knots coincide (a jump, e.g. a double knot for \(p = 1\)), \(\lambda_i = 0\), which forbids the jump; fewer repeated knots (a kink for \(p \geq 2\)) keep \(\lambda_i > 0\). It requires a B-spline parameterization: with a custom basis, differences of the coefficients do not bound input changes, so the MPC rejects it at construction.
-
Trajectorybounds every sampled change \(\bm{u}_k - \bm{u}_{k-1}\), \(T-1\) rows per input, banded for B-splines and dense for a custom basis. Where theControlPointsrows are already exact (\(p = 0\), and \(p = 1\) with a whole sample step in every knot interval), it uses them instead. It is the only mode for a custom basis, and it omits the changes whose basis row norm is at most \(10^{-9}\) times the largest. As withTrajectoryinput bounds, its many rows can make OSQP slower on long horizons.
When you may want to use it:
- Your system is physically limited in how fast it can change inputs
- You want to smooth the input trajectory or avoid large input steps
General Linear Constraints
Set num_general_constraints (\(n_h\)) to constrain linear combinations of the state and input at every step, with setGeneralConstraints(Hx, Hu, h_min, h_max), and num_terminal_constraints (\(n_{h,\mathrm{f}}\)) to constrain the final predicted state, with setTerminalConstraints(Hf, hf_min, hf_max).
This is the usual stage and terminal split: \(\bm{x}_0\) is the measured state passed to solve(), so the \(k = 0\) constraints limit \(\bm{u}_0\) given \(\bm{x}_0\), each predicted state \(\bm{x}_k\) with \(k \geq 1\) is paired with \(\bm{u}_k\), and \(\bm{x}_T\) (which has no input) is covered by the terminal constraints.
Pass -inf or inf for a side without a bound.
Rows of the identity in \(H_x\) with \(H_u = 0\) (plus the same terminal rows) give state limits, and \(H_x = 0\), \(H_u = I\) limits every sampled input.
Changing \(H_x\), \(H_u\), or \(H_{\mathrm{f}}\) rebuilds QP matrices and makes OSQP refactor, like a model change; changing only the bounds is cheap. With the condensed formulation, as with the model, an entry of these matrices that may become nonzero later must be nonzero when the solver is initialized; the sparse formulation keeps every entry in its sparsity pattern (see Runtime Updates).
When you may want to use it:
- Limits on outputs or combinations of states, e.g. \(y = C\bm{x}\) within bounds
- Constraints that couple states and inputs, e.g. a power or friction-cone limit linearized at the operating point
- Terminal constraints, e.g. reaching a target set at the end of the horizon
Danger
A constraint row without an input part (a zero row of \(H_u\)) only checks the measured state at \(k = 0\), so the problem is infeasible whenever \(\bm{x}_0\) violates it, as with hard state bounds. OSQP can also need many iterations when more constraints are active than there are control points.
From MPC to QP
The next two pages provide the missing steps:
- Input Parameterization derives the parameterization basis matrix \(\Psi^p(\bm{\tau})\).
- QP Formulation stacks the prediction model and converts the full MPC problem into quadratic-program form.